Street-Level Snapshot
Picture this: graveyard shift, pallets stacked like brick walls, clock ticking while a picker waits. You can almost hear the wheels grinding. The amr controller is blinking green, but the flow’s still stuck. Ops logs in big sites often show double-digit minutes lost each shift to handoffs and reroutes, and that ramps up fast when zones get tight. So why does a system built to move keep stopping? Is it maps, radio noise, or the way commands get pushed down the line (yeah, all of the above)? We’ve got a mix of Wi‑Fi black spots, human overrides, and bots arguing over path rights. That’s the street-level truth in motion—messy, loud, and real. So here’s the question: what’s actually missing in the control loop that should keep all that chaos in check? One hint: coordination is a system problem, not a single-bot flex. Let’s line up the usual fixes against the new stack and see what holds under pressure—then we move to the deeper cut.
Old Fixes, New Load: Where Traditional Control Stalls
Look, it’s simpler than you think: legacy stacks break at the seams. The core issue with older setups isn’t the sensors or the motors; it’s the glue logic between them. With amr control as the lens, you can see how polling loops, vendor-locked APIs, and brittle waypoint scripts choke when fleets scale. A PLC fires commands; a bot follows; but the environment shifts every second. Wi‑Fi hiccups turn into stale commands. SLAM updates are delayed. Then the fleet scheduler punts, because the queue can’t see dock congestion in real time. You get jittery PID loops fighting drift while the CAN bus fills with noise. Edge computing nodes sit underused, while the cloud tries to arbitrate QoS across busy zones—funny how that works, right?
Back to the dock scene from Part 1: one forklift swings wide, two bots recalc, and a third freezes at a blind corner. Traditional scripts don’t model lane priority or battery swaps by intent. They can’t bind sensor fusion to live traffic rules. And they almost never speak EtherCAT end-to-end, so timing slips. The result is human-in-the-loop patches, more overrides, and a slow bleed of minutes. That’s the hidden pain point: the system treats navigation as a bot skill, not a fleet behavior. When demand spikes, the old playbook breaks first.
Principles That Push Us Forward
What’s Next
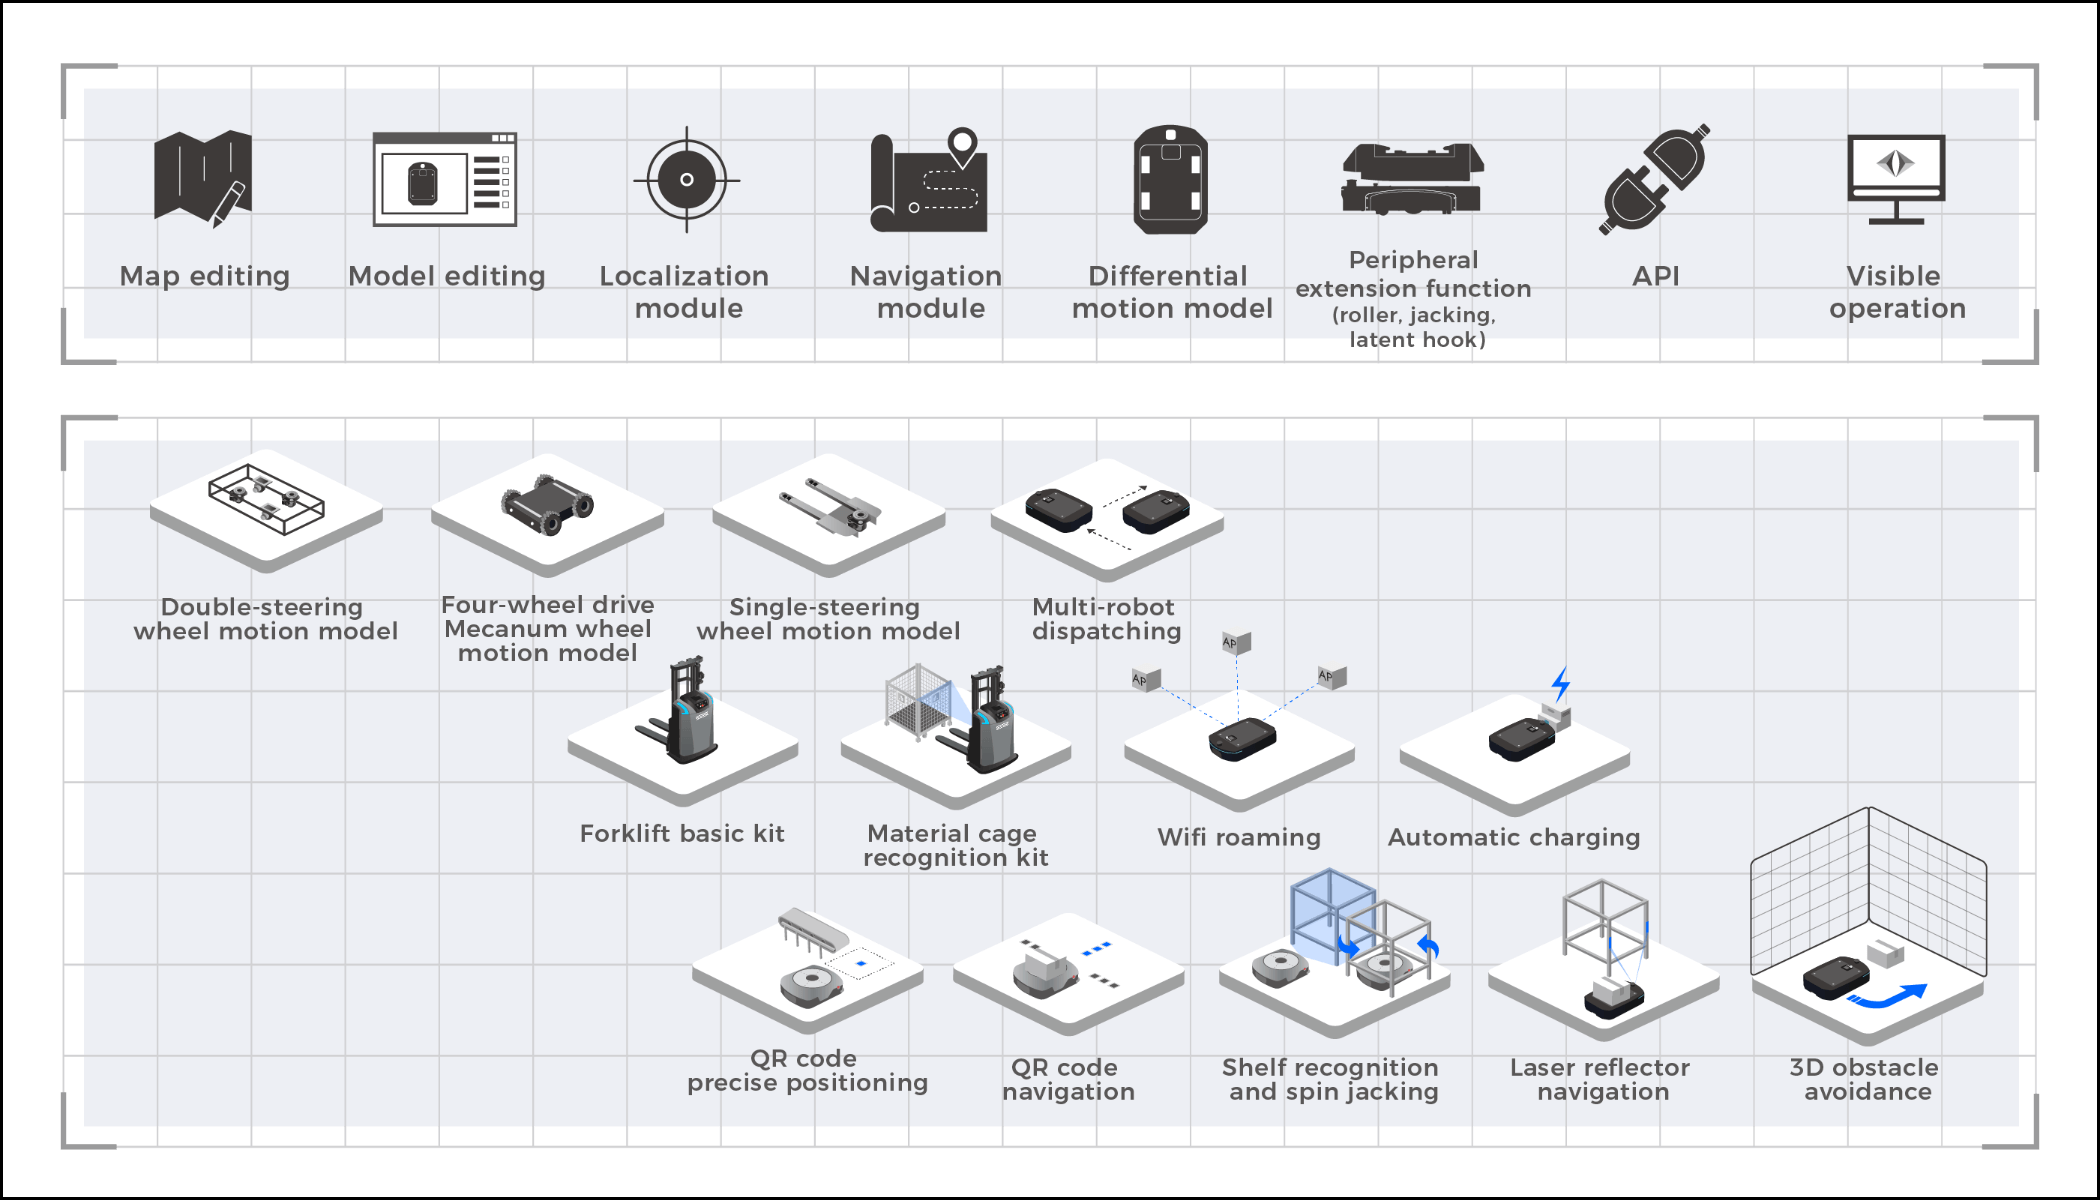
The next wave leans on first principles: event-driven orchestration, intent-level planning, and tight timing. Modern amr control frameworks model the floor as a living system. Commands flow as state changes, not dumb routes. Edge coordination watches zones, batteries, and dock queues. Then it allocates tasks with traffic shaping, like a city grid for robots. Sensor fusion isn’t just for maps; it feeds fleet policy in real time. You cut jitter by pushing micro-decisions to edge computing nodes, while the cloud sets guardrails. Power converters, motors, and brakes get synced with deterministic buses, so latency becomes predictable. And when a lane clogs, the trajectory planner re-schedules tasks, not just paths. Different vibe from Part 2? A bit—it’s semi-formal here, because the stakes are scale and uptime. Also, it maps. Hard.
Compared to the old stack, you get fewer overrides, cleaner handoffs, and better use of floor space—without more rules to babysit. The lesson so far: treat control as a system fabric, not a single controller box. Summing it up without repeating ourselves: old scripts stumble on change; new orchestration absorbs it. If you’re choosing a solution, evaluate three things: 1) timing integrity across the stack (edge to motor, including EtherCAT/CAN), 2) fleet-level policies with measurable QoS under load, and 3) transparency in diagnostics, from SLAM health to trajectory planner decisions—funny how clarity tends to speed things up, right? For teams that want a steady, non-hyped path forward, keep your eyes on vendors who build that fabric and prove it in mixed fleets, like SEER Robotics.